Liquid AI LFM3 Review: Open-Weight Multimodal Models and On-Device Options
Review summary
Liquid AI released six LFM3 open-weight multimodal models on October 27, 2026. The review examines their architecture, deployment options, and pricing structure.
Liquid AI LFM3 review focuses on the six open-weight multimodal models released October 27, 2026. Each model contains roughly 2 billion parameters and targets specialized tasks on phones, laptops, and edge hardware rather than general-purpose scale.
The family branches from a shared LFM3-1.7B-Base backbone pretrained on 22 trillion tokens using a tri-hybrid architecture that combines gated convolutions, sliding-window attention, and global attention layers.
Liquid AI LFM3 Architecture and Capabilities
The six models share the same core but differ in modality support and output format. LFM3-1.7B handles text input and output with 256K context. LFM3-VL-2B adds image and video input for 128K context. LFM3-Audio-2B supports text and audio input plus text and speech output across 18 languages at 32K context. LFM3-Omni-2B combines text, images, video, and audio for multimodal input and text or speech output at 32K context. The d1-2B and d1-Omni-2B variants produce calibrated structured outputs such as probabilities and bounding boxes instead of free-form text.
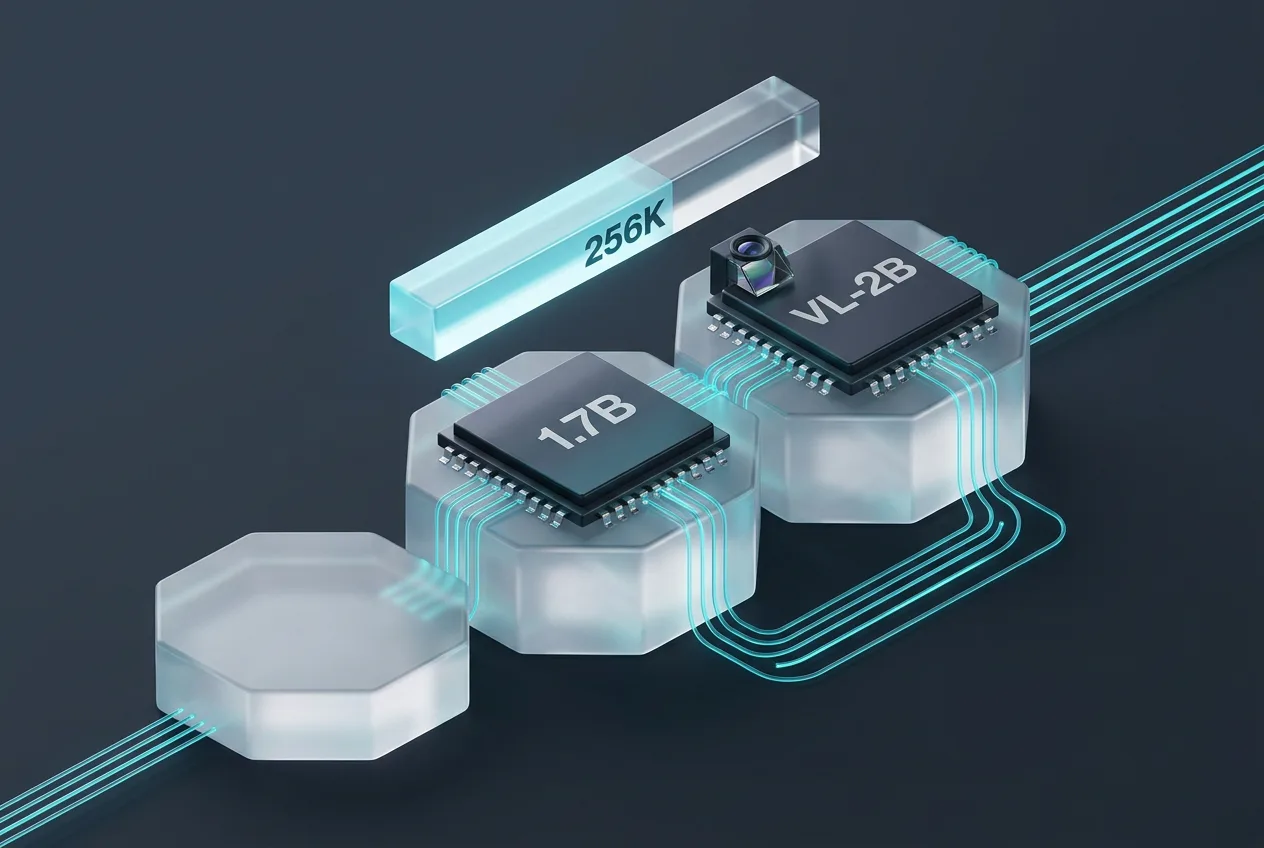
Performance figures come from vendor benchmarks. LFM3-1.7B scores 49.37 on average across 29 benchmarks, ahead of Qwen3.5-9B at 47.24. On agent tasks it records 38.42 on WebArena-Verified and 41.29 on AutomationBench. LFM3-VL-2B averages 71.4 across 62 vision benchmarks, matching Gemma 4 12B results. The models are not positioned for complex multi-step reasoning or agentic coding due to their compact size.
Deployment options emphasize local and on-device use. Quantized 4-bit GGUF versions occupy about 1 GB. Supported runtimes include llama.cpp, MLX, ONNX, Transformers, vLLM, and SGLang. Early tests show 43.6 tokens per second generation on an iPhone 17 Pro using 1.9 GB memory. Apple M4 and M5 Max chips, AMD Ryzen AI laptops, Raspberry Pi boards, and Qualcomm NPUs have all run the models successfully. Long-context KV caches for 128K remain under 1.6 GB.
Deployment, Pricing, and Practical Limitations
API access runs through Liquid Console, OpenRouter, and Vercel AI Gateway. Public pricing pages list only older models; authenticated console rates for LFM3 appear around $0.08 per million input tokens and $0.20 per million output tokens, with higher charges for vision and audio tokens. New organizations receive a $2 starting credit. Context windows via API are listed at 128K while model cards allow 256K for the text-only variant.
Licensing uses LFM Open License v1.0, which permits broad commercial use without copyleft on fine-tunes. Companies under $10 million annual revenue and all research or nonprofit organizations may use the weights free of charge. Larger organizations require an enterprise license. Weights are hosted on Hugging Face alongside a web playground.
Early user reports on Hugging Face and technical forums note fast local inference and straightforward fine-tuning on a single GPU. Complaints center on incomplete Ollama and LM Studio vision support at launch and occasional context truncation differences between API and local runs. Independent benchmarks remain limited as of late October 2026.
| Model | Parameters | Modalities | Context | Typical Use |
|---|---|---|---|---|
| LFM3-1.7B | 1.73B | Text | 256K | General text tasks |
| LFM3-VL-2B | 1.92B | Text + vision | 128K | Image and video understanding |
| LFM3-Audio-2B | 2B | Text + audio | 32K | Voice interfaces |
| LFM3-Omni-2B | 2.17B | All modalities | 32K | Multimodal agents |
Compared with Qwen3.5-9B and Gemma 4 12B, the LFM3 family trades parameter count for efficiency and on-device speed. The smaller footprint enables deployment where larger models cannot run, but it requires fine-tuning for domain-specific accuracy. No major security incidents have been reported; the license and hardware requirements remain the primary constraints for enterprise adoption.
Frequently asked questions
How large are the LFM3 models?
Each of the six LFM3 models contains approximately 2 billion parameters, with the base text model at 1.73 billion and the full Omni variant reaching 2.17 billion.
What deployment options exist for LFM3?
Models run locally via llama.cpp, MLX, ONNX, Transformers, and vLLM. Quantized versions fit in roughly 1 GB and have been tested on phones, laptops, and edge devices such as Raspberry Pi.
Is API pricing for LFM3 publicly listed?
Public pages show rates only for prior models. Authenticated Liquid Console users see LFM3 pricing near $0.08 input and $0.20 output per million tokens, with higher costs for vision and audio.
What license covers the LFM3 weights?
LFM Open License v1.0 allows commercial use. Organizations under $10 million revenue and nonprofits receive free access; larger companies need an enterprise license.
Comments 1