DeepSeek API Review: V4 Pricing, Reasoning Benchmarks and Token Limits
Review summary
DeepSeek API offers two main V4 endpoints with large context windows, agentic benchmarks, and tiered pricing that doubles during peak hours.
DeepSeek API provides access to two V4 models through OpenAI-compatible endpoints. The service targets developers building reasoning and agentic applications that require large context windows and competitive benchmark scores. Launched by Hangzhou DeepSeek, the API supports both flash and pro variants with distinct performance and cost profiles.
DeepSeek API Overview and Key Features
The API exposes deepseek-flash, which runs DeepSeek-V4.1-Flash-1017 released in October 2026, and deepseek-v4-pro based on DeepSeek-V4-Pro-0813. Both endpoints accept the standard OpenAI chat format at api.deepseek.com and also support Anthropic-style requests. Flash includes vision input while Pro remains text-only. Users can toggle thinking mode, request JSON output, and invoke tool calls through the Responses API.
Context length reaches 1 million tokens for both models, with a maximum output of 384,000 tokens. Concurrency limits stand at 2,500 simultaneous connections for Flash and 500 for Pro, adjustable through a support ticket at no added cost. The platform records no published per-minute rate limits, instead relying on user_id isolation for traffic management.
Benchmark results show V4.1-Flash-1017 scoring 77.0 on DeepSWE v1.1, 94.5 percent on ARC-AGI-1, 78.1 percent on ARC-AGI-2, and between 90.9 and 93.2 percent on GPQA Diamond. It reaches 42.3 on Terminal-Bench 4.0 after an 11-point gain from the prior build. These figures position the model strongly in long-context coding and agentic tasks, though it trails certain closed models on HLE without tools.
DeepSeek API Pricing, Limits, Benchmarks, and Security
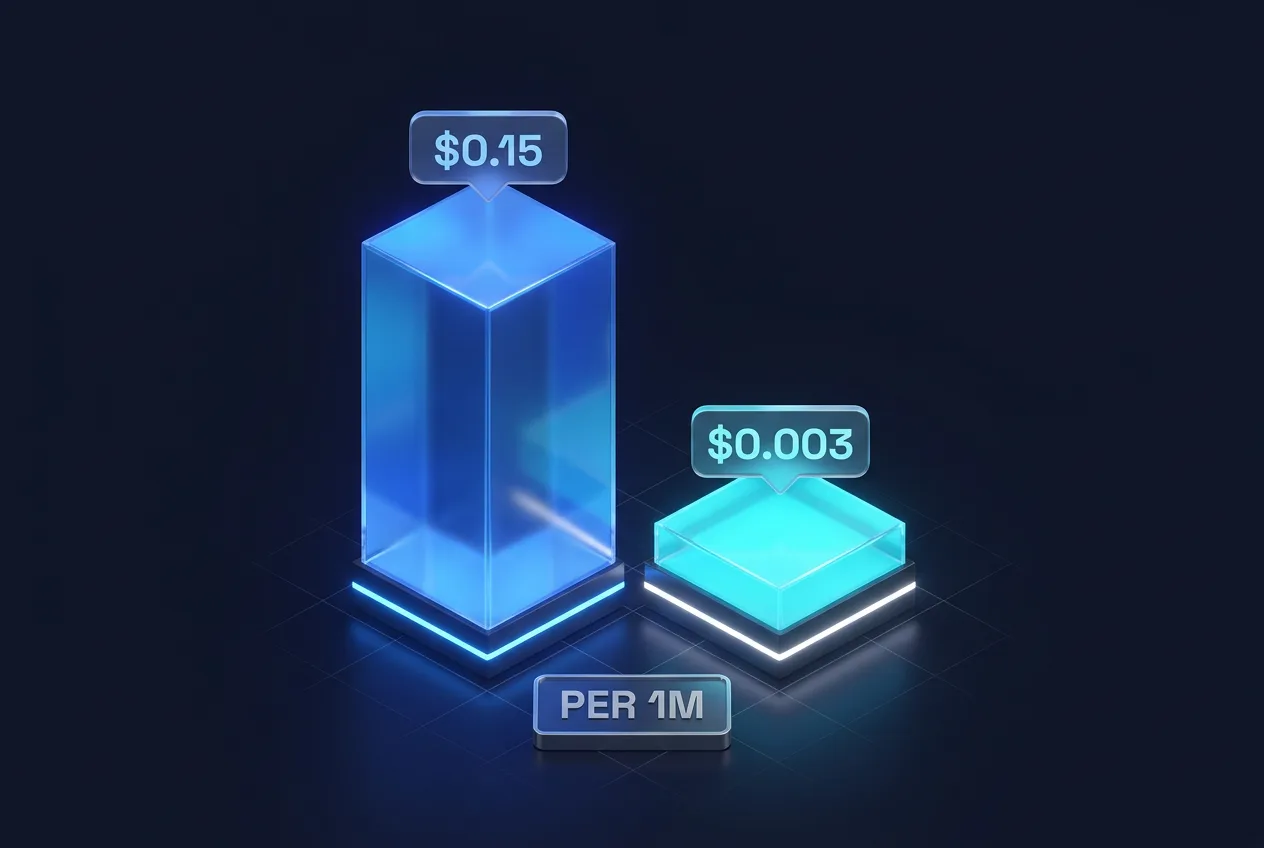
Pricing uses a cache-aware structure measured per million tokens and doubles during peak hours defined as weekdays 01:00–04:00 and 06:00–10:00 UTC. Off-peak Flash rates are $0.15 for cache-miss input, $0.003 for cache-hit input, and $0.60 for output. Peak rates rise to $0.30, $0.006, and $1.20 respectively. Pro off-peak stands at $0.66 cache-miss, $0.022 cache-hit, and $1.98 output, doubling at peak. Separate Search and Fetch APIs bill at $0.75 per 1,000 successful requests since November 1, 2026.
Privacy documentation states that prompts, files, and history are processed and stored in mainland China. Training on user inputs occurs unless disabled through account settings or email request. API terms fall under PRC law, and no SOC 2, BAA, or zero-retention commitments are published. Federal civilian agencies in the United States received a ban on the service in October 2026 due to data-transfer concerns. Regulators in Italy and South Korea have previously restricted similar data practices.
Direct alternatives include third-party hosts of the open weights such as OpenRouter, Fireworks, Together AI, and DeepInfra, which route traffic outside PRC jurisdiction. Comparable hosted models from Anthropic, OpenAI, Alibaba’s Qwen, Meta’s Llama, and Mistral provide different compliance profiles and feature sets. Self-hosting the MIT-licensed weights on infrastructure like AWS Bedrock or Azure allows full control over data residency.
| Provider | Input Cache-Miss (off-peak) | Output (off-peak) | Max Context | Peak Multiplier |
|---|---|---|---|---|
| DeepSeek Flash | $0.15 | $0.60 | 1M | 2× |
| DeepSeek Pro | $0.66 | $1.98 | 1M | 2× |
| Claude 3.5 Sonnet | $3.00 | $15.00 | 200K | none |
| GPT-4o | $2.50 | $10.00 | 128K | none |
Common user complaints center on unpredictable latency during peak windows and the absence of enterprise-grade compliance certifications. Positive reports highlight strong agentic coding performance and the ability to reduce costs through cache-hit traffic and off-peak scheduling. No independent zero-retention audit has been published for the hosted service.
Frequently asked questions
What are the current DeepSeek API pricing rates?
Flash off-peak input cache-miss costs $0.15 per million tokens and output $0.60. Pro rates are higher at $0.66 input cache-miss and $1.98 output. All rates double during weekday peak hours.
Does DeepSeek API support vision inputs?
Only the Flash endpoint accepts image inputs through DeepSeek-V4.1-Flash-1017. The Pro endpoint remains limited to text.
Where is data stored when using the DeepSeek API?
Prompts, files, and conversation history are processed and stored in mainland China according to the published privacy policy.
Are there official alternatives to the hosted DeepSeek API?
Developers can route requests through third-party hosts of the open weights or run the MIT-licensed checkpoints on AWS Bedrock, Azure, or self-managed infrastructure.
Comments
No comments yet. Be the first!